R+AI 2026 Abstracts
Abstracts, bios, titles, affiliations, and headshots will be added as speaker materials come in. To show a photo, add the image file named in the comment under that speaker and uncomment the image line. Talk titles on the program link here. The workshop and tutorial are on their own page.
Andrew Heiss
Ph.D., Assistant Professor of International Politics and Policy, Georgetown University in Qatar
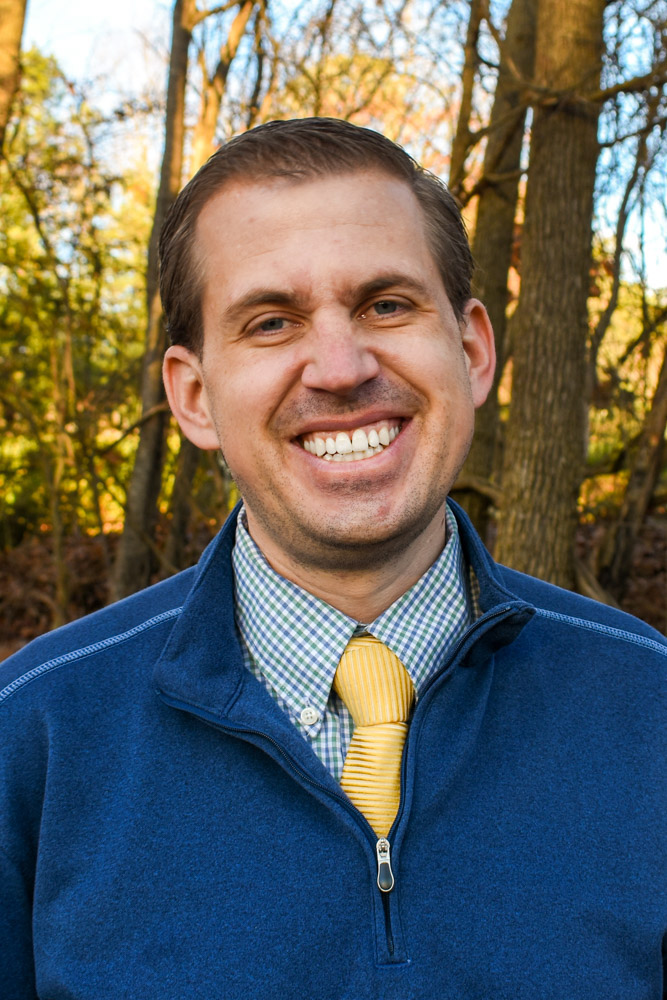
Friction Worth Keeping: What Keeps Us Human When AI Makes Everything Easy
Date & Time: November 10 at 8:00 AM, Eastern
Format: Opening Keynote (45 minutes)
Abstract
Generative AI removes friction. Need a poster for an event? Slides for stakeholders? An R package to access an API? An answer for a problem set? A feature requiring major refactoring? It’s all a prompt away. Incidental, frustrating friction is disappearing.
But not all friction is bad. Some friction is formative and central to the human experience. Struggling to learn develops skills and expertise. Creating things slowly gives us time to reflect and develop taste. Working through hard problems builds understanding and judgment. Contributing to a community builds trust.
AI can eliminate all kinds of friction, producing output that looks polished and convincing whether it’s grounded in human understanding or hollow underneath. How can we tell what friction is worth keeping? This talk explores the difference between friction that gets in our way and friction that makes us who we are, and what keeps us human when our work becomes effortless.
Bio
Andrew Heiss is an assistant professor of international politics and policy at the Edmund A. Walsh School of Foreign Service at Georgetown University in Qatar. Before moving to Qatar, he was an assistant professor at the Andrew Young School of Policy Studies at Georgia State University. He received his Ph.D. in public policy and political science from Duke University’s Sanford School of Public Policy in 2017.
His research examines how international NGOs work in authoritarian countries. He received the 2016–2018 Emerging Scholar Dissertation Award from the International Society for Third Sector Research (ISTR). He also works in public administration and policy, nonprofit management, international relations, and comparative politics.
He teaches quantitative research methods and data science, program evaluation and causal inference, data visualization, economics, and science communication. He is a certified RStudio instructor and a Posit Academy mentor.
Sahana Prasad
Guest Faculty, BITS-WILP, Pilani (India)
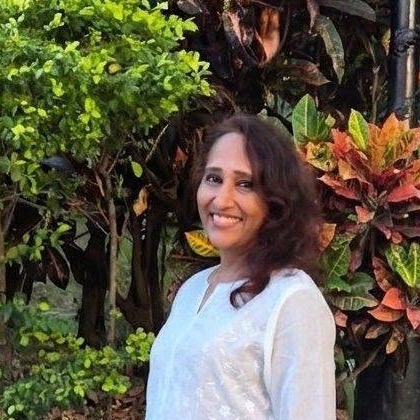
From Statistical Models to Generative AI: Why Statistical Thinking Still Matters in the R+AI Era
Date & Time: November 10 at 8:50 AM, Eastern
Format: Talk (35 minutes)
Topic: Evaluation, Observability, Responsible AI, and Governance
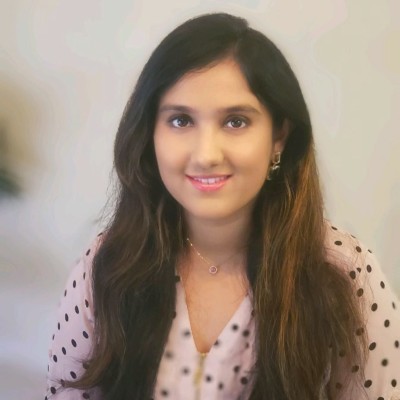
Co-Presenter: Sharanya Prasad, Senior Product Manager, Amazon Web Services
Abstract
Generative AI is rapidly changing how we work with data and write analytical code, including within the R ecosystem. Yet, as AI becomes increasingly capable of generating code, models, visualizations, and analytical narratives, the need for statistical thinking becomes more important—not less.
This talk explores how foundational statistical principles can guide the responsible and effective use of Generative AI in data analysis with R. Through practical examples, we will examine situations in which AI-generated analyses can produce plausible but misleading conclusions, including issues related to data quality, sampling, uncertainty, correlation and causation, model assumptions, bias, and interpretation.
The session will demonstrate how R can serve not merely as a coding environment, but as a tool for independently validating, reproducing, and critically evaluating AI-generated analytical results. We will also consider how the roles of statisticians and data analysts are evolving as AI increasingly participates in the analytical workflow.
The central message is simple: AI can generate code and analytical insights, but statistical thinking remains essential for determining whether those insights are valid, meaningful, and fit for decision-making.
Bio
Sahana Prasad brings more than 35 years of experience across academia, government and industry. She teaches and writes about data science and statistics using R, and has mentored researchers and trained faculty in applied analytics. Her books have been published by Springer Nature and Apress. She is also a recipient of the World Bank Statistical Capacity Building Award. Her work rests on one conviction: statistics earns its keep only when people can understand it, use it and trust it. She regularly publishes in Indian newspapers on varied topics.
Co-Presenter bio
Sharanya is a Senior Product Manager at Amazon Web Services building cybersecurity products. She has a background in networking and cloud having worked at Cisco, HPE previously.
She has experience in cybersecurity, cloud, networking, wireless, and SDWAN and AI, who has led suites of products in the consumer, SMB, and enterprise verticals to deliver business results.
Past Startup founder and believe in being a student and learning for life!
I love to work in environments where I can solve some challenging and meaningful problems, own the solutions end-to-end and work alongside passionate and smart people.
Diana Pholo
Machine Learning Data Scientist (Research)
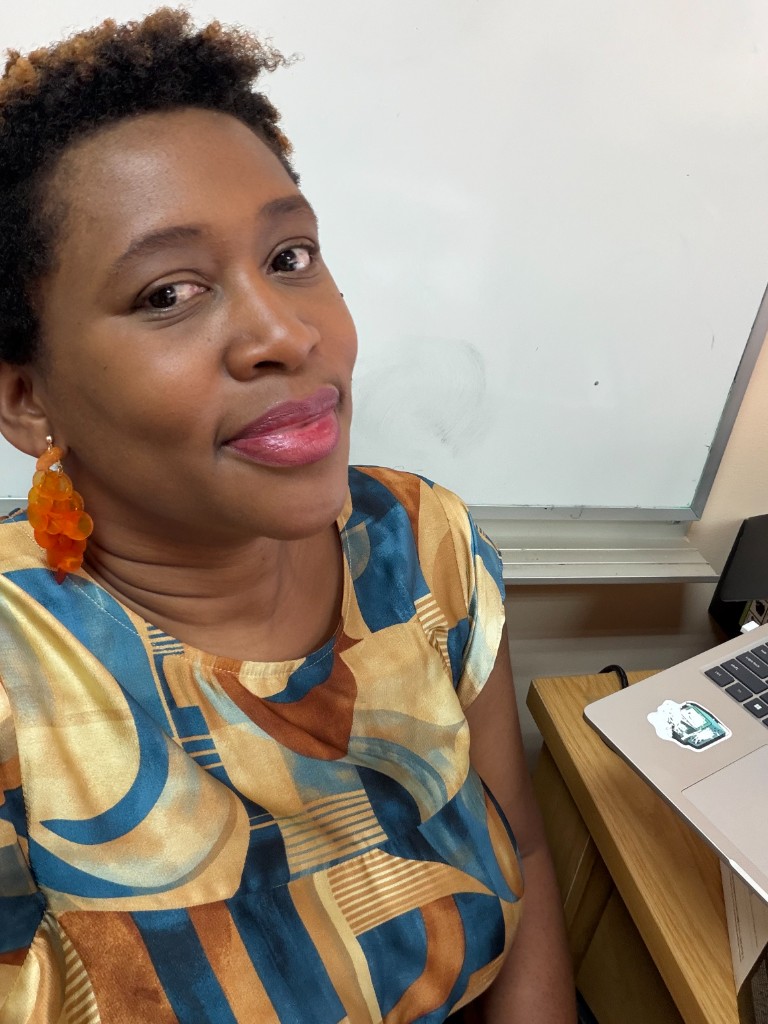
To prompt or not to prompt? Why agentic AI is not the panacea.
Date & Time: November 10 at 9:30 AM, Eastern
Format: Lightning talk (15 minutes)
Topic: Agents, MCP, and Tool Ecosystems
Abstract
Agentic AI is everywhere in 2026, with 40% of enterprise apps expected to embed AI agents by year-end. Every new feature feels like reaching for an agent by default, because the tooling makes it so easy.
At the same time, Gartner forecasts 40% of agentic AI projects may be cancelled by 2027 due to unclear value and huge costs. This lightning talk cuts through the noise by discussing the following: what agents actually are, the levels of autonomy worth knowing, and when a simple prompt or rule beats an agent outright.
Bio
Diana Pholo Stone is a Congolese data scientist and researcher, whose passion is to harness artificial intelligence to address real-world challenges, particularly in Africa.
She holds a Doctorate of Computing degree from the Tshwane University of Technology and currently works in a South African governmental agency while pursuing a post-doctoral fellowship.
Her professional experience spans data science, predictive analytics, natural language processing, and the development of intelligent solutions that support evidence-based decision-making.
Beyond her technical career, Diana is passionate about education, mentorship, and empowering African communities through technology. She believes in making complex knowledge accessible and creating opportunities for others to thrive.
She also has a full-time job as a Chief-Mom-Officer.
Joseph Barbier
Yellow Sunflower
50 lines of code to rebuild Claude Code in R
Date & Time: November 10 at 10:05 AM, Eastern
Format: Talk (35 minutes)
Topic: LLM Engineering in R
Abstract
Claude Code can feel like a complex piece of software, but its core ideas are surprisingly simple. In this talk, I’ll show how to rebuild its essential features in about 50 lines of R code. The result is a small coding agent that can read files, edit code, run commands, and ask for confirmation when needed.
We’ll walk through how it works and see how a simple loop and a few tools are enough to build a coding agent. Along the way, I’ll show how much ellmer handles for us, why it makes R a powerful environment for experimenting with AI agents, and how you can use these ideas to start building your own AI tools in R.
Bio
Joseph Barbier is a data consultant and open-source developer. Through Yellow Sunflower, he helps teams build simpler, more reproducible data workflows. He works primarily with Python, R, and Typst, with a particular interest in data visualization, reporting and accessibility.
Maciej Cabanski
Data Analysis and R Specialist
From Prompts to Pipelines: Building Auditable Human–AI Workflows for Evidence Synthesis in R
Date & Time: November 10 at 10:45 AM, Eastern
Format: Talk (35 minutes)
Topic: LLM Engineering in R
Abstract
Large language models can accelerate evidence synthesis, but using them responsibly requires more than writing good prompts. This talk presents an R-based workflow for integrating LLMs into systematic review processes while preserving reproducibility, traceability, and human oversight. I will show how LLM-assisted screening, full-text assessment, structured data extraction, and normalization of concepts for narrative synthesis can be embedded in a reproducible targets pipeline, with prompt templates, structured JSON outputs, caching, validation checks, evidence quotation, and reviewer-facing quality-control reports. The talk focuses on practical lessons from building an auditable human-in-the-loop workflow and on design patterns that can help researchers move from isolated LLM calls toward more reliable and inspectable AI-assisted research pipelines.
Bio
Maciej is an R programmer and data scientist specializing in research design, reproducibility, and automation.
His work focuses on designing reproducible analytical workflows that combine methodological rigour with statistical programming and software engineering. He develops end-to-end R pipelines for clinical and social science studies, as well as evidence synthesis, using tools such as targets, Quarto, and renv.
His recent projects integrate large language models into systematic review workflows, with particular emphasis on screening assistance, structured evidence extraction, validation, human oversight, and methodological transparency.
He holds a master’s degree in psychology and has co-authored peer-reviewed scientific publications.
His professional interests lie at the intersection of research methodology, research software engineering, and philosophy of science, with a current focus on developing transparent, reproducible, and auditable human–AI research workflows.
Troy Hernandez
Founder and CEO, cornball.ai
Turtles All the Way Down: Recursive Language Models in R
Date & Time: November 10 at 12:05 PM, Eastern
Format: Talk (35 minutes)
Topic: Agents, MCP, and Tool Ecosystems
Abstract
corteza is an LLM agent harness on CRAN. It answers the question, “What if we put an LLM in the R console instead of the command line?” In the literature, CodeAct and Recursive Language Models name this shape; in the market, Prime Agent.
The test case is ARC-AGI-3. With one prompt, corteza scored an official 98.6% on the public set with Claude Opus 5 and 100% with GPT-6 Astra, ahead of Prime Agent’s 95.5%. ARC’s adapter also scores 100% with Astra, but the metrics hide that corteza’s run was better. I’ll show the 894-helper workspace the model built mid-game.
The second recursion is the development loop. This experiment gave corteza a lessons store and thorough tracing of every R call, a dataset about the harness. saber gives an agent the same view of corteza’s code. Next, corteza analyzes data about its own harness and changes it.
Bio
Troy Hernandez is founder and CEO of cornball.ai, where he builds AI tooling in R. Since February 2026 he has published 25 CRAN packages and counting, including corteza, an LLM agent runtime that runs the model inside a live R session.
He earned his PhD in Statistics from the University of Illinois at Chicago in 2013, with a focus on applied machine learning, following an MS in Statistics and undergraduate degrees in mathematics and philosophy. Before founding cornball.ai he spent seven years at IBM as an Executive Architect and open source analytics evangelist, and worked as a data scientist at Civis Analytics, VivaKi, and Sears Holdings. He was a postdoctoral researcher at Tsinghua University and an AI advisor and mentor to NASA’s Frontier Development Lab. His research has appeared in PLoS ONE, the Journal of Computational Biology, and Transportation Research Record.
Troy has organized the Chicago R User Group since 2016, mentors early-career data scientists and developers, and shares his work through talks, tutorials, and posts at cornball.ai and troyhernandez.com.
Ashley Geldmeier
Data Scientist I, ACES
Self-Documenting Shiny Applications with GitHub Actions, ChatGPT, and Playwright MCP
Date & Time: November 10 at 12:45 PM, Eastern
Format: Talk (35 minutes)
Topic: Agents, MCP, and Tool Ecosystems
Abstract
When you build a Shiny application with Golem, you can structure it a lot like an R package. You can write tests with testthat, document your functions with roxygen2, and keep things like a README, NEWS file, and user guide alongside the code. That is great until the application starts changing faster than the documentation does.
In this talk, I’ll show how GitHub Actions, the ChatGPT API, and Playwright MCP can work together to handle a lot of that maintenance automatically. That includes updating documentation and tests, checking whether user workflows have changed, and creating new tutorial videos when they are actually needed. The goal is to spend less time chasing documentation updates and more time improving the application, while still keeping everything aligned with the code.
Bio
I am a data scientist who loves solving problems that scale. I build tools and systems that help teams stop starting from scratch so they can focus on higher value work. I blend data science, software engineering, and automation to drive reproducibility, process optimization, transparency, and reliable model outputs. My goals are to enable better decisions and remove process bottlenecks. I work mainly with R, Python, and SQL.
Kerrigan Baron
CTO & Co-Founder, Fidget Labs B.V.
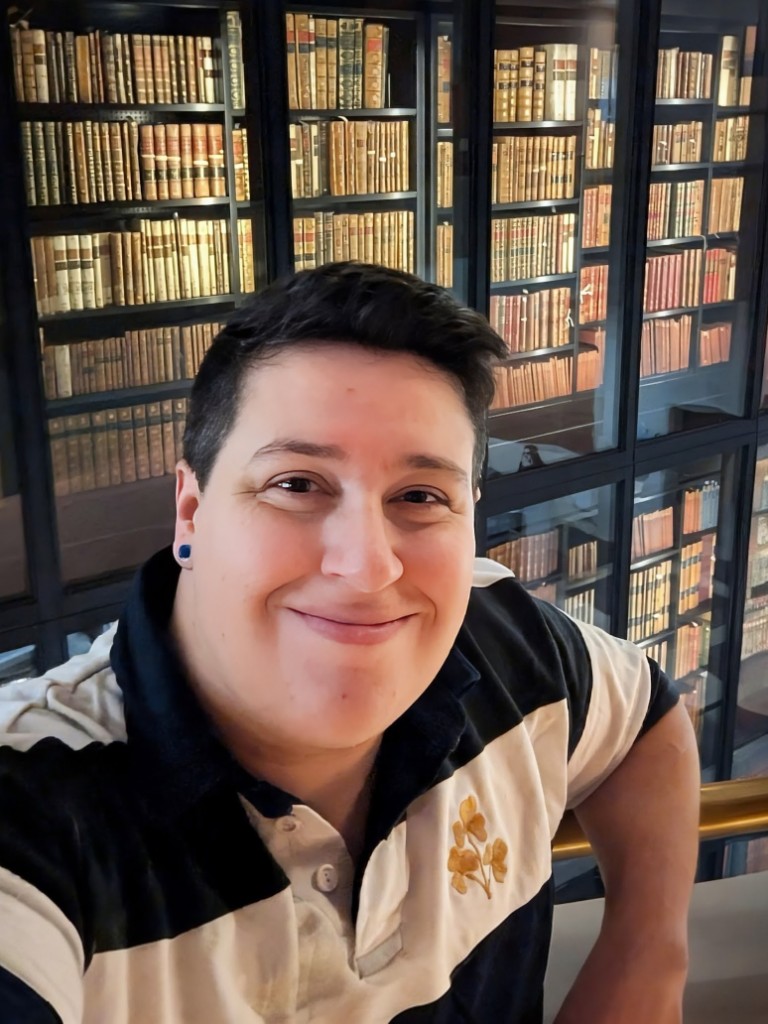
Ten Agents, 8GB of RAM, and Ten Dollars a Month
Date & Time: November 10 at 1:25 PM, Eastern
Format: Lightning talk (15 minutes)
Topic: Agents, MCP, and Tool Ecosystems
Abstract
Ten AI agents run the back office of my consultancy. They track the market, draft content, triage my inbox and supervise each other, mostly while I sleep.
They run on a refurbished office desktop. 8GB of RAM, two hundred euros, five to ten dollars a month. The spec forbids Docker, Redis and any cloud database. The constraint did the design work.
Anyone can stand up agents now. Far fewer people talk about night forty, when the agents have been faithfully writing to a shared memory nobody is tidying and three quarters of it is repetition.
Three decisions determine whether a system like this still earns its keep a month in, and none of them are about the models. Where the memory lives. Who cleans it up. What establishes a fact before a model is allowed to interpret it.
No code on screen, no R required, no prior agent experience assumed. If you decide where AI goes in your organization, these are your decisions too.
Bio
Kerrigan Baron (they/them) is CTO and co-founder of Fidget Labs, a composable architecture and AI enablement consultancy. They have twenty years of enterprise delivery for brands including J.P. Morgan Chase, AstraZeneca, Trimble, REI and Konica Minolta.
They lead delivery for the MACH AI Exchange under contract with the MACH Alliance Tech Office, a vendor-neutral program where enterprises, integrators and vendors co-develop the agentic patterns that hold up in production. Kerrigan runs its monthly agentic AI sessions and leads its hackathons, architecting and shipping builds with IPSY, Wegmans, Dr. Martens, easyJet Holidays and Your Golf Travel. Every prototype is released open source for the ecosystem to use.
Kerrigan has spoken at Netlify Compose and Contentful Storylines, writes Focal Point, and advocates for LGBTQIA+ inclusion in technology.
LinkedIn · Bluesky · YouTube · fidgetlabs.io
Imad El Badisy
Research Engineer in Biostatistics, Mohammed VI Center for Research and Innovation (CM6RI)
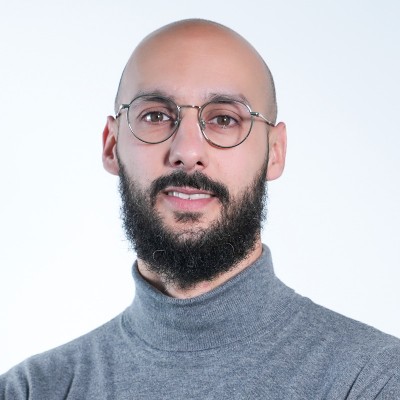
Agentic Compactness: Measuring the Cost of AI-Generated Machine Learning Workflows in R
Date & Time: November 10 at 1:45 PM, Eastern
Format: Talk (35 minutes)
Topic: AI-Assisted R Development and Coding Workflows
Abstract
As AI coding agents increasingly build and repair machine learning workflows, the design of an R framework affects more than developer convenience. This talk introduces agentic compactness: the operational simplicity of a workflow measured through code length, framework calls, functions, objects, and package dependencies. Using matched classification and regression tasks, I compare funcml, mlr3, and tidymodels under shared learners, hyperparameters, data splits, validation, and scoring. The workflows achieve identical predictive performance but differ substantially in structural complexity, loading time, and memory use. A clinical genomics application demonstrates how funcml’s seven-verb interface supports an extended analysis. The talk concludes by showing how this benchmark can be extended to autonomous coding agents using first-run success, repair loops, and token consumption.
Bio
Imad El Badisy, PhD, is a health data scientist and computational methodologist at the Mohammed VI Center for Research and Innovation (CM6RI), Rabat, Morocco.
He builds open-source software for machine learning and computational biostatistics, turning advanced statistical methods into reliable tools that researchers can use. He holds a PhD from Aix-Marseille University (SESSTIM) on missing data and machine learning for survival analysis.
His research covers scientific machine learning, survival analysis, missing data imputation, and agentic data science: LLM-based agents that plan and run statistical workflows, and software designed so these agents can use it correctly, reproducibly, and safely. He maintains several R packages on CRAN, including funcml.
LinkedIn · elbadisyimad.com · GitHub
Nykko Vitali
PhD Student, Department of Psychology, Harvard University
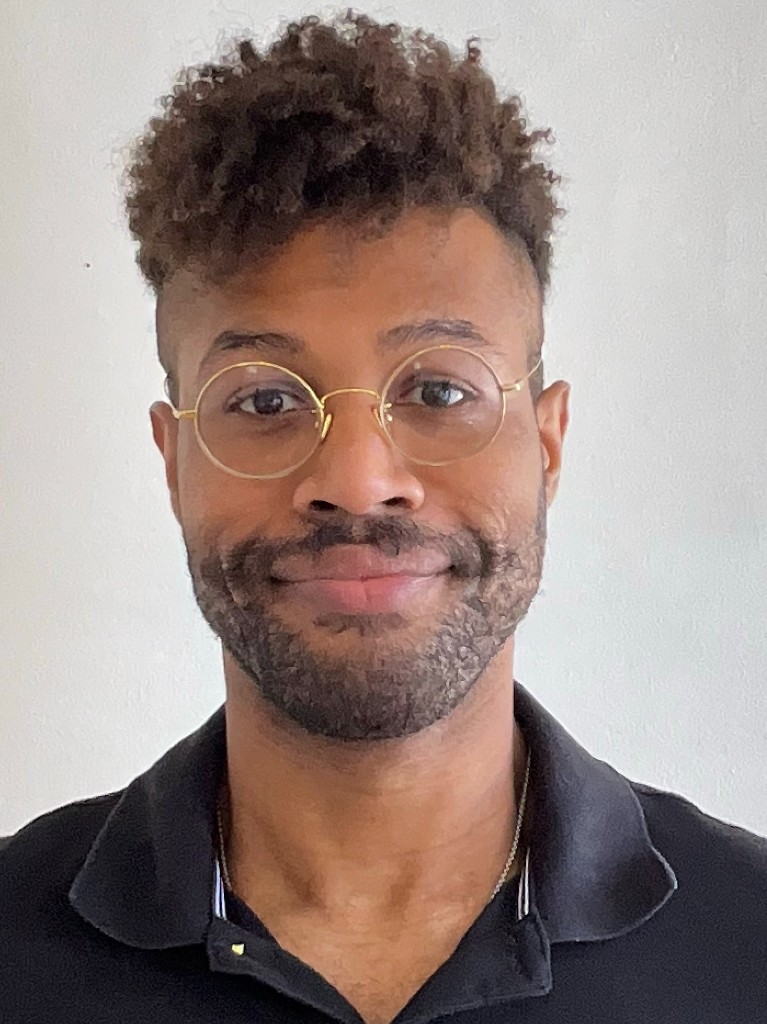
Utilizing Reproducible Agents in RStudio - A Researcher’s Toolkit
Date & Time: November 10 at 3:00 PM, Eastern
Format: Talk (35 minutes)
Topic: Agents, MCP, and Tool Ecosystems
Abstract
ClaudeR is an R package and MCP server that connects AI agents to a live RStudio session.
The agent can code alongside you, act autonomously, guide you as you learn, edit select portions, annotate data, or check code claims against a manuscript—to name a few features. Every line it runs is logged and associated to the agent that ran it, and checkpoints make any step the agent takes reversible. Several agents from different sources (Claude Code, Codex, Antigravity, Cursor, etc.) can share one session and coordinate through a consensus gate, or independent agents can work silo’d in parallel. Whatever your workflow is, the goal of this package is to accommodate it. This talk covers the architecture, how to use it, some example workflows, and what building it taught me about working with agents.
Bio
Nykko Vitali is a PhD student in the Psychology Department at Harvard University. Nykko’s research focuses on decision making under uncertainty in environments where LLMs may be present. He also examines the behaviors, both good and bad, that have seeped into models through pre- and post-training. Nykko built ClaudeR shortly after Anthropic released the Model Context Protocol (MCP), to explore agentic coding within a controlled harness. A year and a half later, the package supports auditable autonomous coding workflows, multi-agent coordination, manuscript reproducibility checks, and data annotation, among other tools for researchers. It now works with Python and Positron as well as R and RStudio, and has 350 GitHub stars. The goal throughout has been to let any MCP-capable LLM work inside RStudio while keeping an auditable script of what was done and when.
Karthik Chandrasekaran
Principal Engineering Manager, Microsoft
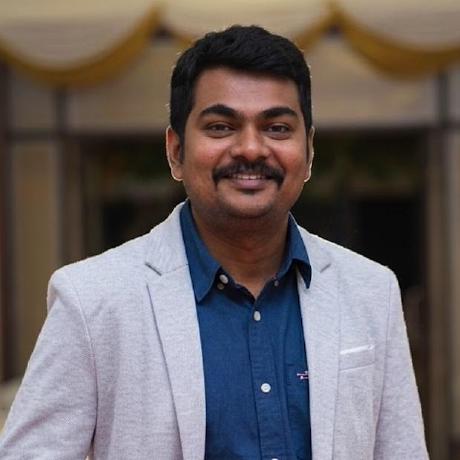
Enterprise AI Governance and Secure Grounding: Privacy, Zero Trust, and Observability in Agentic AI Systems
Date & Time: November 11 at 8:00 AM, Eastern
Format: Talk (35 minutes)
Topic: Evaluation, Observability, Responsible AI, and Governance
Abstract
Deploying production-grade Copilot and agentic systems requires moving beyond basic prompt engineering to tackle complex challenges in data privacy, access control, and system observability. When AI agents dynamically query enterprise data stores and invoke external tools, traditional security boundaries quickly break down.
This session explores proven architectural patterns for enforcing Zero Trust security, privacy-preserving retrieval, and robust observability across enterprise AI platforms. Attendees will discover how to implement secure grounding layers that prevent data leakage and ensure granular access control during vector search and context retrieval. We will also examine strategies for continuous evaluation, tracking prompt and tool regressions, and monitoring system latency and performance at scale.
Whether integrated with Python microservices, R-based analytics platforms, or hybrid enterprise architectures, attendees will gain actionable frameworks to build, deploy, and govern secure, transparent, and resilient AI systems in production.
Bio
Karthik Chandrasekaran is a Principal Software Engineering Manager at Microsoft, where he leads engineering strategy and intelligent agent query-matching platforms for Microsoft 365 Copilot. His technical leadership focuses on Retrieval-Augmented Generation (RAG), vector search infrastructure, cloud-native architecture, and secure identity authentication frameworks.
Prior to Microsoft, Karthik held senior engineering leadership roles at Apple, Capital One, and PayPal, directing core identity systems, security infrastructure, and large-scale distributed platforms. An IEEE Senior Member, he actively contributes to the broader research and technical community through peer reviewing and program committee service for international conferences, including ICITCE, ICETICS, ISCI, and ICCA. Beyond research and industry infrastructure, Karthik is dedicated to STEM outreach and mentoring through organizations such as ADPList.org, University of Arizona programs, Microsoft Early Careers, and UT Austin STEM Girl Day. He holds a Master’s degree in Information Systems Management from the University of Arizona and a Bachelor of Engineering from Anna University.
Lovekumar Patel
Delivery Manager, Data & AI Solutions, ProCogia
R-Native Private AI for Sensitive Data: Secure Analysis and Code Modernization
Date & Time: November 11 at 8:40 AM, Eastern
Format: Talk (35 minutes)
Topic: AI-Powered Data Products and Conversational Analytics
Co-Presenter: Andey Nunes-Brewster, Data Interoperability Coordinator, Oregon Health Authority
Abstract
Almost every AI product assumes data can travel to the model. In public health and other regulated environments, that assumption breaks down. In this joint session with the Oregon Health Authority, we present a different model: bring AI into the analyst’s R environment rather than sending sensitive data out. Using PolyKode Assistance as the implementation, we show private AI integrated directly into the R IDE, supporting exploratory analysis, code generation, Shiny development, and modernization of legacy analytical code, while prompts, data, and outputs stay in the controlled environment. Attendees leave with a view of how to introduce AI into existing R workflows without abandoning the tools and controls they already rely on.
Bio
Lovekumar Patel is an enterprise data and AI delivery leader focused on translating business strategy into practical, scalable solutions and measurable outcomes.
As Delivery Manager, Data & AI Solutions at ProCogia, he leads client engagements from problem definition through implementation and adoption. He aligns executives, technical teams and delivery stakeholders around clear priorities, connecting business requirements with architecture and engineering decisions while maintaining accountability for delivery quality.
With more than seven years of experience across consulting and technology, he has supported organizations in financial services, telecommunications, healthcare, and the public sector. His cross-industry experience and leading infrastructure and data science teams give him a practical perspective on moving data and AI initiatives from concept into sustained operational use.
He bridges business and engineering, combining technical fluency with delivery discipline to build trust across teams and help organizations realize lasting value from their data and AI investments.
Co-Presenter bio
Andey Nunes is a public health data modernization leader advancing how health systems use trusted, interoperable, and equitable data to improve decision-making and public health outcomes.
At the Oregon Health Authority, Andey serves as a Data Interoperability Coordinator, where he contributes to statewide data modernization efforts focusing on governance, interoperability, and collaboration across informatics teams. His work helps build foundations for public health data to move effectively across systems, organizations, and analytical environments.
Previously, as a Data Equity Research Analyst, Andey supported analytical processes, business rules, data quality controls, and governance practices for Oregon’s REALD and SOGI data systems, enabling more responsible use of demographic data to identify and address inequitable health outcomes.
With a background in systems science and environmental science, Andey brings a systems-thinking approach to public health analytics, connecting data governance, interoperability, equity, and analytics to help shape a connected, trusted, and actionable public health data ecosystem.
Zahra Esfandiar
Strategic Analysis Specialist, Saman Electronic Payment (SEP)
SurvSure: Building an Evidence-Grounded, Verified AI Copilot for Survival Analysis in R Shiny
Date & Time: November 11 at 9:20 AM, Eastern
Format: Talk (35 minutes)
Topic: AI-Powered Data Products and Conversational Analytics
Abstract
SurvSure is an evidence-grounded and verification-oriented AI copilot for survival analysis built in R Shiny. The system is designed to move beyond generic AI-generated statistical advice by combining structured survival-analysis workflows with model diagnostics, validation, reproducibility checks, and evidence-based recommendations. The presentation will demonstrate how SurvSure integrates statistical reasoning with AI assistance across key stages of survival modelling, including data assessment, model selection, assumption checking, performance evaluation, and interpretation. The broader goal is to explore how AI can support statisticians and applied researchers while maintaining methodological transparency, reproducibility, and human oversight.
Bio
Zahra Esfandiar is a statistics researcher whose work focuses on survival analysis, statistical machine learning, and the development of reliable data-driven tools for biomedical and real-world applications. Her research explores both traditional and modern survival modelling approaches, including Cox-based models, machine learning methods, deep survival models, and generative approaches. She is particularly interested in reproducible statistical workflows, model evaluation, and the integration of artificial intelligence with rigorous statistical methodology. She is the developer of SurvSure, an R Shiny-based evidence-grounded AI copilot designed to support survival analysis through structured modelling, diagnostics, validation, and transparent statistical reasoning.
Manuel Duval
Scientist, double-strand LLC
Standardizing Molecular Diagnostic Metadata: An Automated Workflow Mapping FDA-Cleared NAAT Assays to Pathogen Taxonomy
Date & Time: November 11 at 10:15 AM, Eastern
Format: Lightning talk (15 minutes)
Topic: AI-Assisted R Development and Coding Workflows
Abstract
The primary objective of the IVD microbial NAAT registry workflow was to bridge the gap between unstructured FDA regulatory labels and validated taxonomic names. Developing this resource required synthesizing expertise across three distinct layers: (i) clinical diagnostics, (ii) pathogen nomenclature, and (iii) bioinformatic search patterns. The resulting mapping was constructed through targeted data normalization steps—ultimately generating a pathogen_synonyms index that successfully translates human-readable clinical text into machine-readable biological identifiers.
Bio
I am a bioinformatics scientist practicing in life science R&D across oncology and infectious disease diagnostics. My work centers on translational pipeline development, genomic data integration, and predictive modeling for biomarker discovery and clinical stratification. I apply R and its ecosystem of packages and data science communication solutions as my primary environment for statistical modeling, multivariate analysis, and open science tool development—authoring custom algorithms, reproducible pipelines, and interactive Shiny applications to streamline high-throughput molecular data processing. My research focuses on translating complex multi-omic datasets into validated, clinically actionable diagnostics to address unmet medical needs in patient care.
Michael Thomas
Chief Data Scientist, Ketchbrook Analytics
Two Languages, One Conversation: An LLM-Powered R Shiny App served by a Python API
Date & Time: November 11 at 10:35 AM, Eastern
Format: Talk (35 minutes)
Topic: AI-Powered Data Products and Conversational Analytics
Abstract
At Ketchbrook Analytics, we’ve built a financial analysis dashboard that allows users to “Chat” with their data in R Shiny. The LLM agent behind it is built in Python. They meet in exactly one place: a streaming API endpoint.
On the Python side, a custom agent explores a curated data catalog, writes SQL, and even reads its own errors and retries.
On the R side, Shiny consumes the API response stream, using ExtendedTask and {future} so the app stays responsive while the model thinks. The user receives a neat data table, a summary analysis, and a custom chart that’s relevant to their prompt.
We’ll cover the “gotchas” we ran into, including how we handled streaming responses with {httr2}, efficiently served custom charts, and cut input costs by 59% through clever caching. The audience will leave with valuable tips and tricks for building an LLM-powered Shiny app.
Bio
Michael Thomas is the Chief Data Scientist at Ketchbrook Analytics, an international data science consulting firm. He holds a Bachelor’s Degree in Accounting and Mathematics from Stonehill College, and a Master’s Degree in Business Intelligence & Analytics from Saint Joseph’s University. He specializes in credit risk modeling and is passionate about bringing strong software development practices to his work. He is highly versed in the R, Python, and SQL programming languages, and holds a certification from RStudio (now Posit) in Data Science Education.
LinkedIn · Bluesky · ketchbrookanalytics.com
Sebastian Fischer
PhD Student, LMU Munich, Munich Center for Machine Learning (MCML)
anvl - Accelerated array computing for R
Date & Time: November 11 at 11:55 AM, Eastern
Format: Talk (35 minutes)
Topic: Machine Learning, Deep Learning, and Multimodal AI in R
Abstract
The {anvl} package is an accelerated array computation framework that brings the same JIT compilation and automatic differentiation technology behind modern deep learning to the R community.
Similar to JAX in Python, users write array programs in plain R, which {anvl} compiles under the hood to optimized machine code using the OpenXLA compiler stack that also underpins frameworks such as TensorFlow and PyTorch/XLA.
Bio
Sebastian Fischer is a PhD Student at LMU Munich. He is a core developer of the mlr3 machine learning framework and is developing anvl, an accelerated array computing framework for R.
Marcin Dubel
Head of Technology, Appsilon
Keep your R workflow in the big AI picture
Date & Time: November 11 at 1:55 PM, Eastern
Format: Talk (35 minutes)
Topic: Agents, MCP, and Tool Ecosystems
Abstract
In the era of AI, R users might feel worry to be left behind. With Mediforce, Appsilon’s open source solution for agentic workflows, we treat all scripts with the same respect. Add your R based analysis to the bigger workflow that includes human actions, other tech stack scripts, with the AI agents on top. Control the execution environment, as well as business approval roles. Audit every action. All the ways to contribute to automation and efficiency.
Bio
Head of Technology at Appsilon, where I’m responsible for engineering excellence, AI innovation, including the Mediforce implementation. I manage the quality of the solutions we deliver to enterprise clients.
I bring 10+ years of hands-on software engineering experience supporting that leadership. A recognized Shiny expert and winner of the 2021 RStudio Shiny Contest Grand Prize, I have deep expertise in R, Shiny, and data visualization. I started with the academic background in statistics and software engineering.
As a member of the Pharmaverse Council, I focus on the Future Focus pillar: exploring how AI and emerging technologies can fill gaps in open-source tooling for clinical trials.
I’m also an active voice in the community, speaking regularly at conferences on Shiny, AI adoption, and building analytical tools that are both powerful and intuitive.
Nammn Joshii
Director, AI Innovation and Delivery, ProCogia
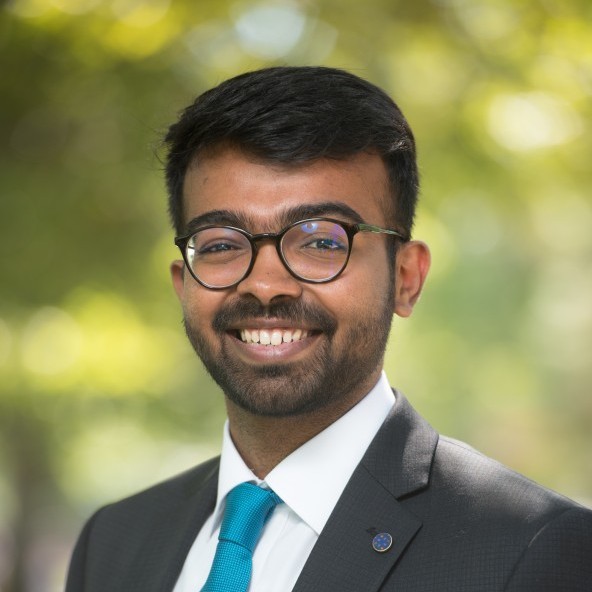
From Experimentation to Trusted Production: A Practical Framework for R+AI in Regulated Industries
Date & Time: November 11 at 2:35 PM, Eastern
Format: Talk (35 minutes)
Topic: Production AI and Industry Case Studies
Co-Presenter: Siddharth Maheshwari, Senior Manager, Data & AI Solutions, ProCogia
Abstract
How do you move an R+AI workflow from a successful experiment into something a regulated organization can actually trust and operate in production? This talk presents a practical, reusable framework for preserving traceability, governance, reproducibility, and control as AI moves into higher-consequence workflows. We will use a deployment spectrum, from public AI services and enterprise APIs through private cloud, on-premises, and air-gapped environments, to show the trade-offs across control, speed, complexity, and cost. The goal is not maximum sovereignty, but choosing the level of control that matches the workload’s risk, value, and scale. Drawing on lessons from regulated analytics modernization and real production workflows, we will show how model selection, evaluation, observability, guardrails, validation, and human oversight fit together in practice. Attendees will leave with a reusable framework and readiness checklist for deciding what to control, validate, monitor, and govern before scaling R+AI.
Bio
Nammn Joshii is Director, AI Innovation and Delivery at ProCogia, where he leads enterprise data and AI transformation, strategic client engagements, and consulting delivery. He advises executives on translating AI, data, and technology strategy into scalable operating models and production-ready solutions that improve performance, reduce costs, and accelerate growth. With 13+ years of experience across technology and transformation, Nammn combines strategic perspective with hands-on delivery experience to help organizations navigate complex, technology-led change and move AI from experimentation into trusted enterprise use.
Co-Presenter bio
Siddharth Maheshwari is Senior Manager, Data & AI Solutions at ProCogia, where he leads strategic engagements helping organizations apply data, analytics, and AI to complex business challenges. With 10 years of experience across consulting and technology, he partners with business and technology leaders from strategy through implementation across telecommunications, logistics, manufacturing, life sciences, technology, and the public sector. Siddharth brings a practical perspective on designing and scaling data and AI capabilities while balancing business value, technical architecture, governance, and organizational considerations.
Mine Çetinkaya-Rundel
Professor of the Practice, Department of Statistical Science, Duke University; Senior Developer Advocate, Posit, PBC
Beyond the prompt
Date & Time: November 11 at 3:15 PM, Eastern
Format: Closing Keynote (45 minutes)
Abstract
AI tools can generate a polished ggplot, scaffold a Quarto report, and debug a dplyr pipeline in seconds. Should students still learn to do these things themselves? I argue yes—and that teaching programming and reproducible workflows is more important than ever. When AI produces plausible code freely, students must be able to assess whether it works as intended, recognize when an analysis quietly goes wrong, and structure their work so every step can be verified. Programming also teaches students to think with data: to ask sharper questions, understand what data can and cannot answer, and reason rigorously about uncertainty and models. Drawing on experience designing introductory data science courses, this talk reframes programming as a pathway to statistical thinking rather than syntax acquisition. Through concrete examples, it explores assignments and assessments that reward genuine understanding and prepare students to use AI critically, reproducibly, and responsibly.
Bio
Mine Çetinkaya-Rundel is Professor of the Practice in the Department of Statistical Science at Duke University and Senior Developer Advocate at Posit, PBC, as well as an affiliated faculty member in the Computational Media, Arts, and Cultures program at Duke University. Her work is dedicated to advancing innovation in statistics and data science pedagogy, focusing particularly on computing, reproducible research, student-centered learning, and open-source education. She emphasizes integrating computation into the undergraduate statistics curriculum, employing reproducible research methodologies, and analyzing real and complex datasets.